
AI and agent development
We build AI features that sit inside a product and carry real responsibility: answering from your own documents, drafting work a person then approves, or taking a multi-step task from request to finished result.
What you get
Answers grounded in your data
Retrieval over your own documents, tickets and records, so the system answers from what your business actually knows rather than from what a model happens to remember.
Actions with explicit boundaries
Agents that call your tools and APIs inside limits you set, with every call logged, so an automated step can be audited and undone rather than merely trusted.
Evaluation from the first week
A scored test set built alongside the feature, so you can tell whether a prompt, model or retrieval change improved the system or only changed it.
How we approach it
The model is rarely the hard part. What decides whether an AI feature survives contact with users is everything around it — how context is retrieved and ranked, what the system is allowed to do, what happens when it is wrong, and whether you can measure any of it. So that is what we build first: retrieval over your data, explicit tool and action boundaries, logging of every prompt and response, and an evaluation set that can tell you whether a change made the system better or merely different.
It also means being straight about where AI does not belong. A deterministic rule, a search index or an ordinary form is often the better answer, and saying so in week one is far cheaper than discovering it after launch.
Problems this solves
A demo that does not survive real users
Prompt-only prototypes impress in a meeting and then meet the long tail of real questions. What closes the gap is retrieval, guardrails and evaluation, not a longer prompt.
No way to tell whether it is any good
Without an evaluation set, every change is a guess and every regression is discovered by a customer. Quality becomes an opinion rather than a number.
Inference cost that scales badly
Spend climbs faster than usage when every step calls the largest model. Caching, routing and smaller models for the simple parts keep it proportional to value.
How we work

Ideate
We collaborate with clients to define goals, explore ideas, and create a clear plan for a successful software solution.

Develop
Our team builds robust, scalable applications using modern technologies and best development practices.

Maintain
We provide ongoing support, updates, and optimizations to ensure your software remains reliable and efficient.

Scale
We help your solution grow with your business by enhancing performance, adding features, and supporting larger user bases.
What this includes
Products we designed, built, and still run.
Our portfolio showcases projects delivered with expert craftsmanship and exceptional quality.
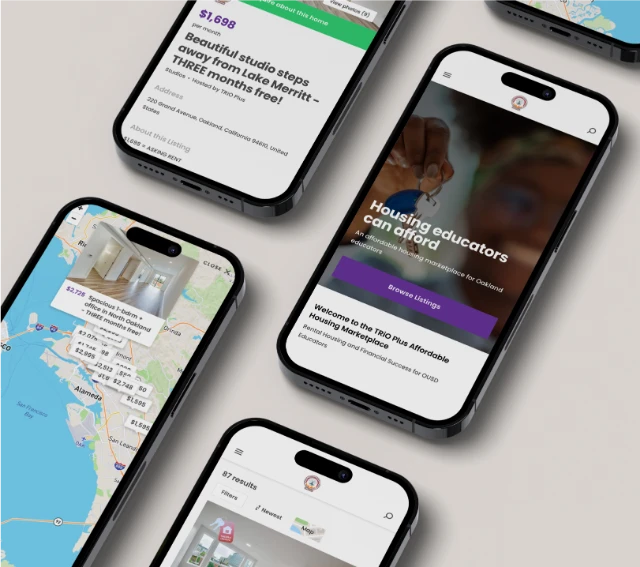
Housing platform for educators
Affordable housing discovery for teachers, with mapped inventory, eligibility screening and landlord onboarding.
- React
- Express
- PostgreSQL
- Mapbox
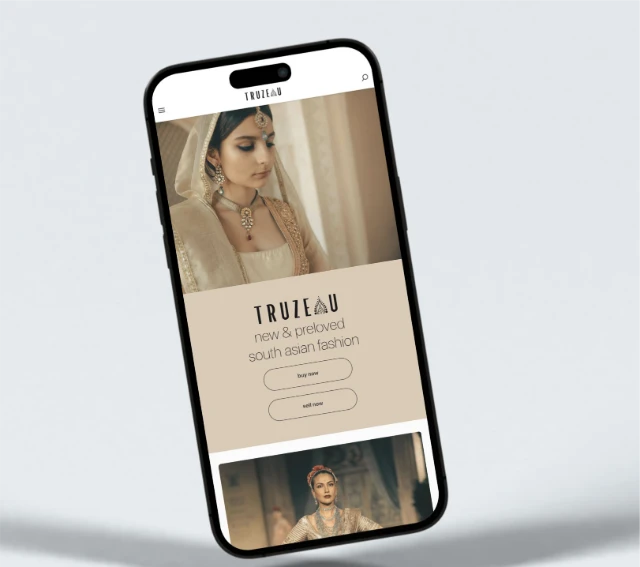
New & preloved fashion marketplace
Seller onboarding, condition grading and an editorial storefront tuned for mobile-first browsing.
- React
- Node.js
- Stripe
- AWS
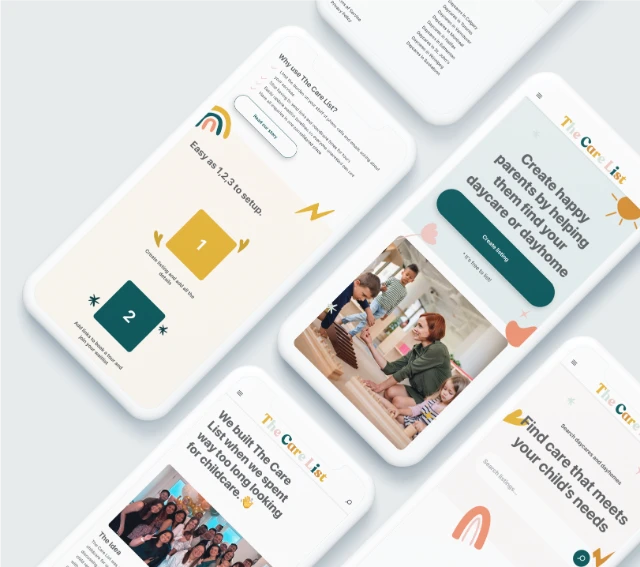
Childcare discovery and booking
Helps families find and book the right daycare, with licence verification, availability and enquiry management for providers.
- React
- Node.js
- MongoDB
- Twilio
Questions we get asked
What can an AI feature realistically do inside our product?
Reliably: answer questions from your own content with citations, draft work a person reviews, extract structure from messy input, and carry out multi-step tasks against your own APIs. Less reliably: anything where being confidently wrong is expensive and no human checks the output. We design for the first set and put a review step wherever the second is unavoidable.
Do we need to train or fine-tune our own model?
Almost never at the start. Retrieval over your data plus a capable general model answers most product needs, and it is far cheaper to change your mind about. Fine-tuning earns its place for consistent formatting, a narrow classification task, or cost reduction once traffic justifies it — after an evaluation set exists to prove it helped.
How do you stop it inventing answers?
Four things together: ground every answer in retrieved passages, cite them so a reader can check, give the system an explicit way to say it does not know, and score all of that on a test set before release. Hallucination cannot be driven to zero, so the design question is what happens when it occurs, not whether it will.
How do we start without committing to a large build?
With a scoped pilot against one real use case, including the evaluation set, so the result is evidence rather than a demo. Our AI pilot engagement runs four to six weeks and ends with a working feature, its scores, and an honest recommendation — which is sometimes that the problem does not need AI.