
Data and ML engineering
An AI feature is only as good as the data reaching it. We build the ingestion, storage and retrieval layers that keep a model working from information that is current and that you can vouch for.
What you get
Pipelines that announce their own failure
Scheduled ingestion with monitoring and alerting attached, so stale data is something you are told about rather than something a user finds.
Retrieval that returns the right passage
Vector and keyword search tuned together and measured on real queries, because neither alone finds what people actually ask for often enough.
Models you can keep watching
Training and serving with the monitoring needed to notice drift, so a model that has quietly stopped matching the world gets caught early.
How we approach it
This work is unglamorous and decisive: pipelines that move data on a schedule and say so loudly when they fail, schemas that survive the next requirement, and retrieval that combines vector and keyword search because neither alone returns the right passage often enough. Getting it wrong shows up later as an assistant that confidently quotes last quarter.
Where conventional machine learning is the better tool than a language model — ranking, classification, forecasting — we train and serve those too, with the monitoring needed to notice when a model has quietly drifted away from the world it was trained on.
Problems this solves
A live feature answering from stale data
An assistant that confidently quotes last quarter is worse than no assistant. Freshness is a pipeline problem, not a prompt problem.
Search that misses the obvious
Pure vector search fails on exact terms, part numbers and names; pure keyword search fails on meaning. Most real retrieval needs both, scored against real queries.
Nobody can answer where a number came from
When metrics are assembled by hand from exports, two reports disagree and neither can be traced. Lineage has to be built in, not reconstructed afterwards.
How we work

Ideate
We collaborate with clients to define goals, explore ideas, and create a clear plan for a successful software solution.

Develop
Our team builds robust, scalable applications using modern technologies and best development practices.

Maintain
We provide ongoing support, updates, and optimizations to ensure your software remains reliable and efficient.

Scale
We help your solution grow with your business by enhancing performance, adding features, and supporting larger user bases.
What this includes
Products we designed, built, and still run.
Our portfolio showcases projects delivered with expert craftsmanship and exceptional quality.
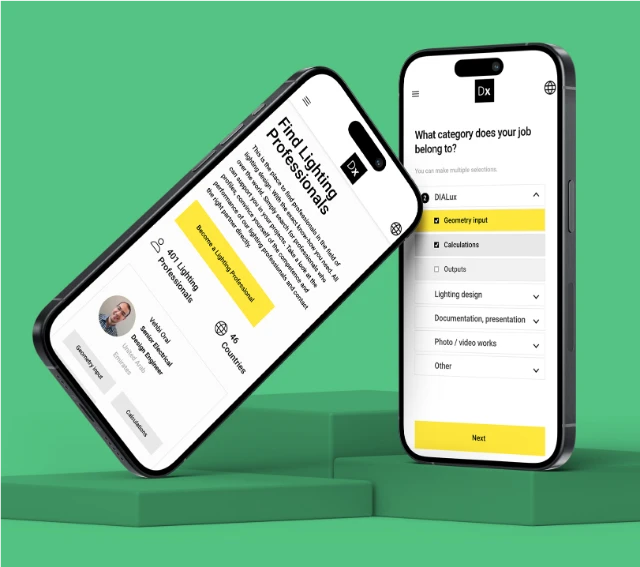
Marketplace for lighting design experts
A two-sided marketplace connecting specifiers with certified lighting professionals worldwide — verified profiles, project briefs and direct contracting, with payouts handled end to end.
- React
- Node.js
- Stripe Connect
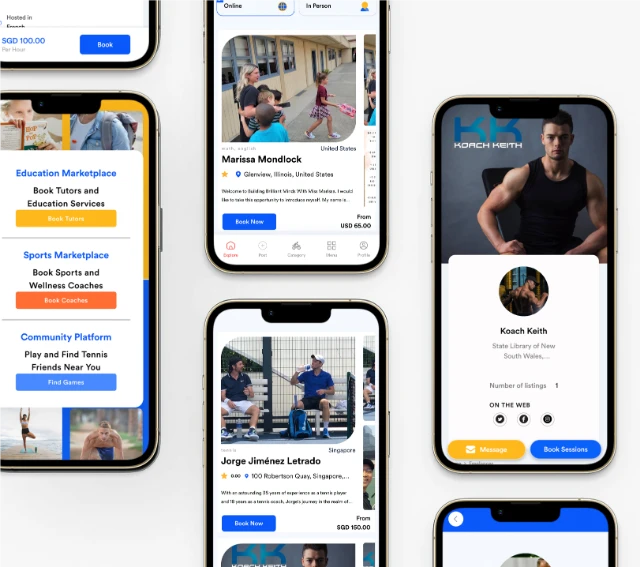
Booking platform for sports, wellness and tutoring
A booking platform where customers find verified sports, wellness and tutoring experts, see real-time availability and pay in one flow.
- React Native
- Node.js
- MongoDB
- Stripe
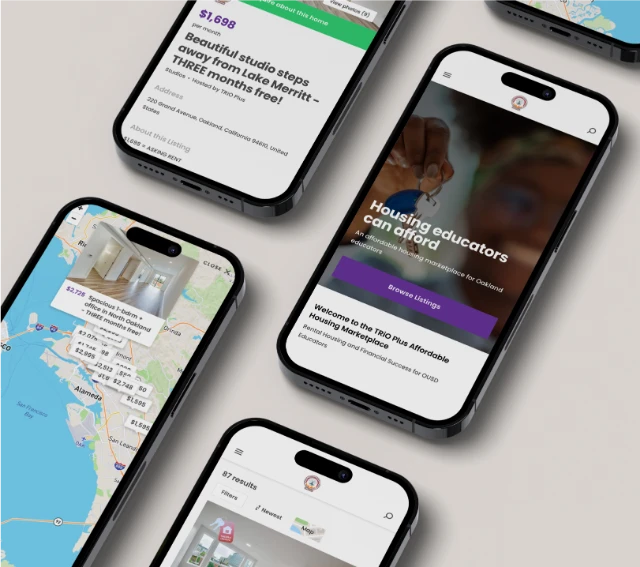
Housing platform for educators
Affordable housing discovery for teachers, with mapped inventory, eligibility screening and landlord onboarding.
- React
- Express
- PostgreSQL
- Mapbox
Questions we get asked
What does an AI feature actually need from our data?
Less than people expect, and in better shape than they expect. A narrow, current, well-described slice beats a large messy one: the documents that answer real questions, chunked sensibly, with metadata for filtering and permissions, refreshed on a schedule. Most projects spend more time on access and freshness than on modelling.
Do we need a warehouse before we can do anything?
No. A warehouse is worth building when several teams need to query the same history; it is overkill for one product feature. We start from the question you need answered and build the smallest pipeline that answers it reliably, then grow that into shared infrastructure if demand appears.
Vector search or keyword search?
Both, almost always, combined and re-ranked. Vector search handles paraphrase and meaning, keyword search handles exact identifiers, and the hybrid of the two is what makes retrieval feel like it understands the question. We measure the combination on your own queries rather than trusting a default.
How do you handle personal or restricted data?
By keeping permission checks in the retrieval layer rather than hoping the model behaves: a query only ever sees passages the requesting user is entitled to. Beyond that, the usual discipline — minimise what is copied, redact what is not needed, record what is stored where, and keep prompts and responses out of logs that are not secured.